Start free trial

TRUE, BUTSelf-Marked

Weights are out, with conditions

But one benchmark sits close to Opus 5.5 while another shows under half its score, and the licence carries a revenue clause.

“Kimi K3.1 Pro's model weights are out, as an open-weight model that nears top proprietary models.”

Hacker News post, 4 November 2026, and Moonshot AI's model card

25 receipts6 support1 refute18 context
Issue 655 November 20263 min
A customer unrolls a long note taped to an open box.
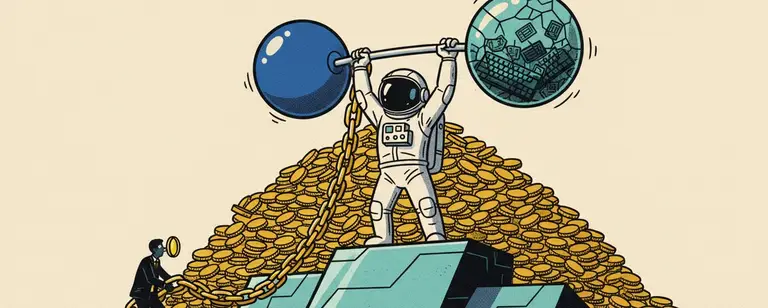
AI illustration

The files are on Hugging Face, and Vals ranks it #3 of 60 on Terminal-Bench 4.0.

20 millionUS dollars of revenue above which a model-hosting business needs a separate agreement
81%Released model's solve rate on Moonshot's internal exploit benchmark
#9Kimi K3.1 Pro's rank of 33 on the Vals Index

There’s more to this story.

Membership opens the full investigation, the strongest counterargument and what to do with what you’ve learned.

30 days free, then A$89 a year. Payment card required. Cancel before the trial ends to avoid the first charge.

Start free trial →
  1. At sign-up: 30 days free. Payment card required. One introductory trial per customer.
  2. Your trial ends 30 days after you start. Unless you cancel before then in Account → Manage subscription, we charge A$89 for the first year. It renews automatically at A$89/yr until cancelled.
  3. You can ask for a full refund within 14 days after any annual payment, renewals included, with no reason needed, by emailing [email protected]. This voluntary refund does not limit your rights under the Australian Consumer Law.

By starting your trial, you agree to the Terms.

Inferno Tech Pty Ltd t/a BS Killer, ABN 27 647 413 474

Already a member? Sign in

The trick has a name

We call it Self-Marked: graded by the party that benefits from the grade. You'll see it again. Learn to spot it →
Say this in tomorrow's meeting“The weights are really out, and it's strong on some tests. It's #3 on Terminal-Bench 4.0 at Vals but #9 of 33 on the Vals Index. And open here comes with a revenue clause for big hosts.”

Receipts

  1. Supports huggingface.co: Kimi K3.1 Pro is an open-weight, natively multimodal agentic model
  2. Supports huggingface.co: Terminal-Bench 4.0 65.7 57.9 58.2 66.4 42.3 41.8
  3. Refutes huggingface.co: Program Bench 31.5 53.5 50.0 65.0 29.1 19.0
  4. Context huggingface.co: the aggregate revenue of the Licensee and its affiliates exceeds 20 million
  5. Context huggingface.co: must enter into a separate agreement with Moonshot AI
  6. Context huggingface.co: "Kimi K3.1-Pro" must be prominently displayed on the user interface
  7. Context huggingface.co: The requirements set forth in Sections 2 and 3 do not apply to: (a) internal use of the Software
  8. Context huggingface.co: Permission is hereby granted, free of charge
  9. Context huggingface.co: in total over any consecutive 12 months
  10. Context huggingface.co: commercial products or services that have more than 100 million monthly active users
  11. Context huggingface.co: operates a Model as a Service business
  12. Supports vktr.com: Kimi K3.1 Pro Nears Top Proprietary Models as Moonshot Limits Its Cyber Skills
  13. Context vktr.com: It traced the trend to cyber content embedded in the general mid-training corpus and to cyber tasks in its RL environments, then removed both for the open-weight release
  14. Context vktr.com: On xdev-bench-hard, Moonshot's internal suite of exploit tasks
  15. Context vktr.com: Its self-reported results show a model that leads in some areas and trails noticeably in others
  16. Supports huggingface.co: SWE Marathon v1.1 51.7 45.6 42.5 46.3 40.0 42.5
  17. Context vals.ai: It ranks #9 of 33 models on the Vals Index with 62.52%.
  18. Supports vals.ai: Its best result is #3 of 60 on Terminal-Bench 4.0
  19. Context vktr.com: The released model solved 81%, up from 33.3% for K3.
  20. Context vktr.com: an unmitigated checkpoint solved 90.5% of problems
  21. Supports vktr.com: ahead of GPT-6 Astra (58.2%) and narrowly behind Claude Opus 5.5 (66.4%)
  22. Context vktr.com: Several of the evaluations Moonshot cites are internal benchmarks that have not been independently verified.
  23. Context vktr.com: not to release open weights that would extend the absolute frontier of cyber capability
  24. Context vktr.com: It also plans to gradually raise the cyber capability available in open weights
  25. Context huggingface.co: Benchmark Kimi K3.1 Pro (max) Claude Fable 5.1 (max, w/ fallback) GPT-6 Astra (max, w/ fallback) Claude Opus 5.5 (max, w/ fallback) DeepSeek-V4.1-Flash-1017 (max) GLM-5.3 (max)

Open the Receipts Pack → What each source proves, every figure traced, and what would change our verdict.

Checked by AI at the BS Killer desk · ruled 5 Nov 2026 · How we check →

Get tomorrow's check in your inbox.

One AI claim a night, checked against independent sources, receipts attached. Free.

Free email updates. Unsubscribe any time.

This story is a stable, citable object. If you can falsify a verdict, tell us. Corrections are loud here.