Start free trial

Five minutes.
AI, made clearer.

What changed, what holds up, and why it matters. A short edition you can actually finish.

Read the briefing

Start with two full samples. Sign in for this edition’s free story. Sources and corrections stay open.

What the pen marks mean
  • rememberThe takeaway: what to remember
  • figureThe number that matters
  • evidenceThe evidence line
  • rulingThe ruling
  • claimThe claim that fails

Each mark is drawn once, as you reach it. Numbers are only circled when they come from the story’s own figures.

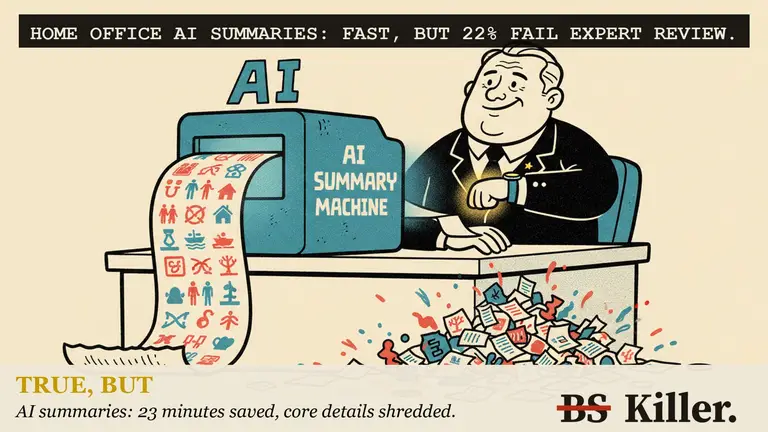
The Home Office's asylum AI failed 45 of 203 expert checks after rollout. Experts checked about 0.3% of the summaries.

A lone inspector lifts one sheet with tweezers from a flood of summaries rushing past on a conveyor belt.
AI illustration

Open Rights Group published Home Office figures showing 45 of 203 sampled AI interview summaries failed the first-stage expert check after the tool was rolled out in April 2026.

The reality check

The pilot evaluation reported 9% inaccurate and 23 minutes saved per case. The field sample shows 22% failing, covers about 0.3% of summaries, and lets summaries that omit details pass.

Why care? Asylum decisions rest on what applicants said. The tool's field accuracy is known only from a 0.3% sample, it fails more than twice as often as in the pilot, and omissions are not counted as failures.

Take this with youAfter rollout, Home Office experts failed 45 of the 203 asylum AI summaries they checked, more than double the pilot's 9%, and they checked about 0.3% of them.

Open the evidence4 source pages

The claim we checked

AI summaries of asylum interviews save Home Office decision-makers 23 minutes per case, with only a small proportion (9%) of summaries found inaccurate in the pilot.

These are quoted receipts, not a count of independent investigations. Several reports may rely on the same original source.

gov.uk ↗
the pilots suggest that the ACS tool could save 23 minutes per case when reviewing interview transcripts
gov.uk ↗
A small proportion of summaries produced (9%) were deemed to be inaccurate or had missing information
openrightsgroup.org ↗
In a first-stage SME check on 203 summaries, 139 passed, 19 were flagged for further review, and 45 failed (22%).
openrightsgroup.org ↗
Just 0.3% of total generated summaries between April-July were checked by Home Office Subject Matter Experts (SME).
theregister.com ↗
summaries could pass the checks even if they omitted important details, as long as the information they did include was accurate.
Open this check in the full collection →
The idea, illustrated01

What was actually checked

  1. 01Pilot: 9% of summaries inaccurate, 23 minutes saved per case
  2. 02Rollout: about 70,000 summaries, April to July 2026
  3. 03Checked: 203, of which 45 failed the first stage
Conceptual illustration · not a data chart
Next: Gemini 4 Carbon's #1

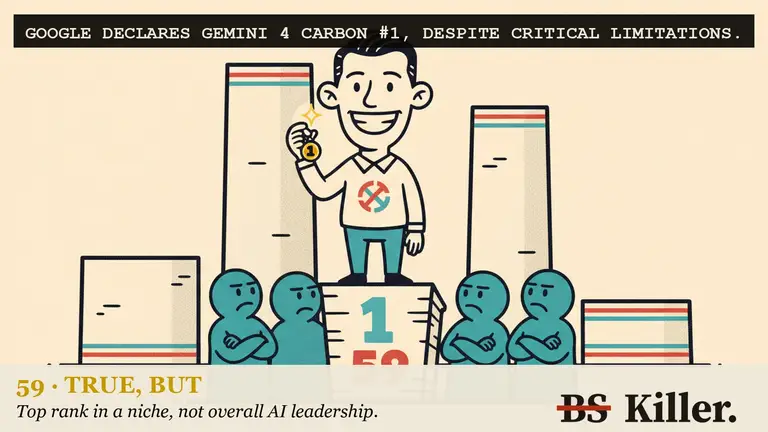
Gemini 4 Carbon is #1 on Artificial Analysis, and the tester agrees. It leads 4 of the 9 tests, and most people cannot use it yet.

A runner holds a giant trophy on a podium in front of a partly lit scoreboard while the stadium gates stay chained to the waiting crowd.
AI illustration

Google launched Gemini 4 Carbon and said it ranks #1 on Artificial Analysis Intelligence Index v5 at 59.

The reality check

Artificial Analysis confirms the #1, with the top score in 4 of 9 evaluations, and says Carbon does not lead coding or knowledge work and is not yet publicly available. Google's own post puts it #4 on WebDev Arena.

Why care? A composite #1 is not a #1 on your task, and a model you cannot call does not change your stack this week. Check the sub-score for your work and budget on the standard $4 / $20 price.

Take this with youCarbon tops the Artificial Analysis index overall but leads only 4 of its 9 tests, and is not yet publicly available.

Open the evidence4 source pages

The claim we checked

Google's Gemini 4 Carbon ranks #1 on Artificial Analysis Intelligence Index v5, making it the best AI model available.

These are quoted receipts, not a count of independent investigations. Several reports may rely on the same original source.

blog.google ↗
Carbon ranks #1 on the recently updated v5.0 of Artificial Analysis Intelligence Index at 59.
artificialanalysis.ai ↗
Gemini 4 Carbon leads the Intelligence Index v5, with the #1 score in 4 of the 9 Index evaluations
artificialanalysis.ai ↗
Carbon makes substantial gains elsewhere but is not leading in coding and knowledge work
blog.google ↗
Carbon jumps +89 elo points to land at #4 (1768) on WebDev Arena
blog.google ↗
Starting this week, we will make Carbon available to a subset of cyber defenders
artificialanalysis.ai ↗
Gemini 4 Carbon is being rolled out to selected users and is not yet publicly available.
blog.google ↗
at $2 per million input tokens and $10 per million output tokens
blog.google ↗
After the introductory period expires, the price of $4 per 1M input tokens and $20 per 1M output tokens will apply.
artificialanalysis.ai ↗
All our charts and figures use standard pricing for both Gemini 4 Carbon and Argon.
artificialanalysis.ai ↗
On average, it costs $7.76 per task to evaluate Gemini 4 Carbon (High) on the Intelligence Index.
artificialanalysis.ai ↗
somewhat expensive when comparing to other models of similar price. It's also faster than average, however very verbose.
news.ycombinator.com ↗
Gemini 4 Carbon | Hacker News
Open this check in the full collection →
The idea, illustrated02

What the #1 covers

  1. 01#1 on one composite index, score 59
  2. 02Leads 4 of 9 tests; not coding or knowledge work
  3. 03Selected users only; standard price $4 / $20
Conceptual illustration · not a data chart
Next: Opus 5.5 on ProgramBench

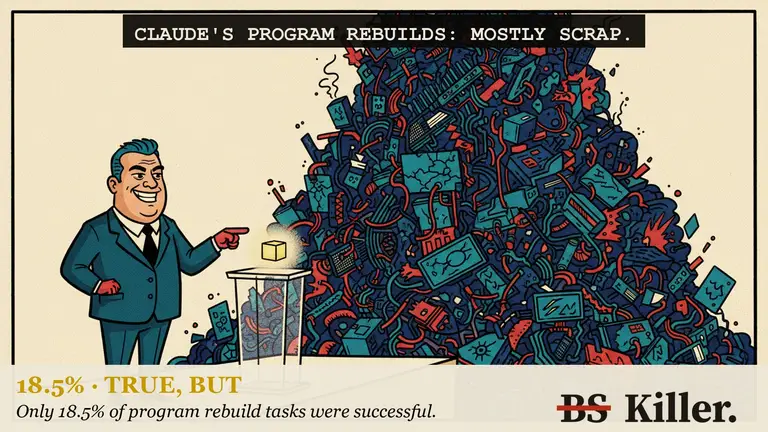
Claude Opus 5.5 hit 18.5% on ProgramBench, up from zero in May. It cloned 37 programs it could run and probe.

A robot carpenter builds a copy of a working music box beside the original while an inspector checks only a few keys.
AI illustration

A trending post said Opus 5.5 can rebuild real programs from scratch, citing 18.5% on ProgramBench after 0% in May.

Free with your account

Sign in for this free check.

This edition’s selected free story opens after sign-in.

Open the evidence3 source pages

The claim we checked

Claude Opus 5.5 can now rebuild real programs from scratch: 18.5% on ProgramBench, up from 0% in May.

These are quoted receipts, not a count of independent investigations. Several reports may rely on the same original source.

vals.ai ↗
Claude Opus 5.5 ranks first on ProgramBench with 18.50%
programbench.com ↗
Given only a compiled binary and its documentation, agents must architect and implement a complete codebase that reproduces the original program's behavior.
arxiv.org ↗
We evaluate 9 LMs and find that none fully resolve any task
vals.ai ↗
a task is counted as Fully Resolved only when the submitted implementation passes all tests.
vals.ai ↗
Claude Opus 5.5 87.0% 130 37
programbench.com ↗
The agent can run the given program with any input and observe exactly what it does
programbench.com ↗
Note that behavioral tests can never cover all possible inputs.
programbench.com ↗
ranging from small terminal utilities like jq and ripgrep to massive software projects like the PHP compiler
arxiv.org ↗
Models favor monolithic, single-file implementations that diverge sharply from human-written code.
Open this check in the full collection →
The idea, illustrated03

Go inside the check.

    The full explanation appears when your reading access is confirmed.
    The finish line

    Edition complete

    You’re up to speed.

    That’s the 29 Oct 2026 briefing. Keep the useful bits. Leave the noise.

    Reading estimate: 511 words at 200 words per minute. Source quotes and the optional sections below add reading time.

    Have another 3 minutes? · Learn one thing

    Tokens: the pieces AI reads

    Two words can be two tokens. One word can be six. See what changes. A beginner lesson with a visual you can play.

    Try the free lesson →

    Keep exploring

    All research

    Browse every checked claim by topic.

    A curated directory. Check each entry’s date and sources.

    Make a little room for clarity.

    Get the next checked edition in your inbox.

    Free email updates. Unsubscribe any time.